2 From Scripts to Data Products
A useful data product is more than a saved table. It has a stable identity, a clear meaning, explicit expectations, and a repeatable way to produce an accepted result.
2.1 The central flow
For the current DataRaft API, the most useful mental model is:
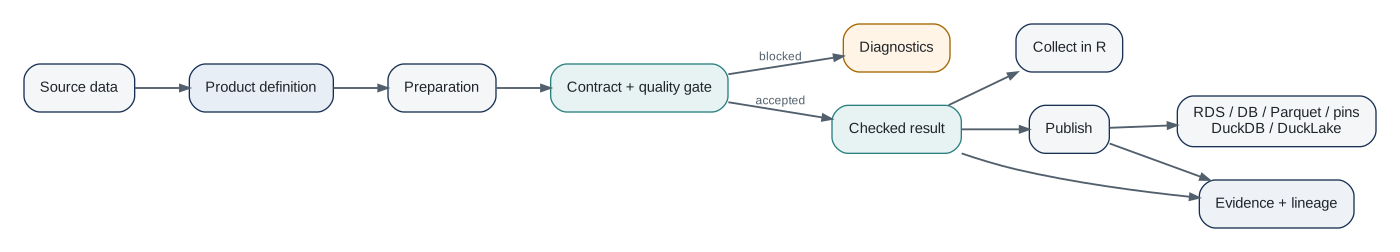
There are two design choices hidden in this picture.
First, definition and execution are separate. Constructors such as dr_product(), dr_contract(), and dataraft.core::dr_recipe() build ordinary R values. They do not need to read data. Execution happens later through dr_run() or dr_publish().
Second, logical meaning and physical storage are separate. A contract can be useful without a lake. A quality rule can run on an in-memory table. A target is an adapter attached to a product, not part of the product’s business meaning.
2.2 A product, not a pipeline
The term pipeline often emphasizes ordered computation. DataRaft uses a product as the center because the same delivery needs more than computation. It needs expectations and evidence.
A product can include:
- one or more sources;
- a contract;
- quality rules;
- a recipe or other transformation components;
- metadata such as owner and description;
- governance policies;
- an optional target;
- input and output port declarations.
Not every product needs every component. Progressive disclosure is part of the design.
2.3 Product state is different from data state
Suppose the policy product is defined once and run every month. The definition changes only when the meaning changes. The incoming rows change every month. Each attempt has its own status and evidence.
This is why dr_product() returns a definition and dr_run() returns a run result. The result has a status such as completed, published, cached, blocked, error, or missing in the current execution code.
A failed result cannot be collected as accepted data. The failure itself remains useful because it carries quality information and can be retained as the session’s last failure.
2.4 What DataRaft is not
DataRaft is not a distributed query engine. It does not replace dplyr, DuckDB, dbt, an object store, an enterprise catalog, or an orchestrator. Instead it provides an R-level composition model and protocols that can use those systems.
It is also not a full semantic layer. The experimental dataraft.metrics package is explicit about this boundary: it can define reusable measures and retain evidence for frozen reports, but joins, semantic time grains, additivity, and broad SQL semantics remain outside its scope.
Throughout the book, Implemented means verified in current source code. Experimental means present but explicitly described as experimental. Conceptual means useful architecture language that should not be mistaken for a shipped feature.
2.5 Summary
DataRaft turns a recurring data task into a named product definition. Execution asks whether one delivery satisfies that definition. Storage is optional. This separation lets the same logical product move from a local R session to a broader platform without rewriting the core idea.
2.6 Exercises
- Draw the lifecycle of one recurring table in your own environment from source to consumer. Mark where assumptions are currently implicit.
- Separate the lifecycle into logical choices and physical choices. Which statements would remain true if the table moved from a file to a database?
- Rewrite one transformation-oriented requirement, such as “run this join”, as a consumer-facing expectation about the resulting product.